An Agentic Data Science Story

An Agentic Data Science Story

For a recent collaboration with AIBM, I found myself working with data from the National Survey of Family Growth (NSFG), which I used in several examples in Think Stats. I was reminded of the technical debt I have accumulated while working with this data, and the dread I feel getting back to it. So I decided to make it a case study in agentic data science.

I asked Claude Code to take inventory of the repository, reorganize it, and rebuild the analysis pipeline. Then I asked it to generate a blog post about the process, which is what follows, with my revisions.


The project

Since 2015 I have kept a repository that does one thing: take the National Survey of Family Growth — a large, repeated, nationally representative survey run by the National Center for Health Statistics — and harmonize it across survey cycles so that marriage patterns can be compared over time.

That is more work than it sounds, and it is worth being specific about why, because the difficulty is not where you would expect.

The obvious problem is that the variables move around. A variable that exists in one cycle may be absent from the next, renamed in the one after, or recoded onto a different scale without changing its name. That is tedious but tractable.

The less obvious problem is that the file format and the metadata format both change across cycles, and not in step with each other. Across ten cycles there are two data formats and three ways of describing them:

cyclesdatametadatahow the code reads it
1982, 1988, 1995fixed-width textSAS setup file (.sas)column positions hardcoded by hand
2002–2019fixed-width textStata dictionary (.dct)dictionary parsed at run time
2022–2023SAS binary (.sas7bdat)embedded in the filepyreadstat

The early cycles are the awkward ones. NCHS distributes a SAS setup file — a program, not a data structure, full of PROC FORMAT blocks — and the repository does not read it. Someone [Allen], years ago, opened that file and transcribed the column positions into a Python list by hand:

colspecs = [
    (976 - 1, 982),
    (1001 - 1, 1002),
    (1268 - 1, 1271),
    ...
]

The - 1 on each start position converts from the one-based columns the SAS file uses to the zero-based ones pandas wants. There are dozens of these, and nothing checks them against the setup file they came from.

Then there are the one-off quirks. The 1988 respondent file, as published, contains no line breaks at all — it is a single unbroken run of 30,022,850 bytes, which is 8,450 records of 3,553 characters each. Reading it requires splitting it into records first. And in the 2022–2023 file every variable name is uppercase except one, agebaby1, which is lowercase for no reason anyone has recorded.

The repository grew one cycle at a time. Each new release meant a new loading function — ReadFemResp2002, ReadFemResp2010, and so on — that knew the quirks of that cycle and mapped them onto a common set of columns. Ten cycles for women, seven for men: seventeen loading functions, each a small archive of things learned the hard way.

The output is a survival analysis. For each decade-of-birth cohort, it estimates the fraction who have ever married, as a function of age. Those curves are the reason the project exists, and they show something clear:

Percent ever married, women, as published in December 2024

Each successive cohort marries later than the one before, and the more recent cohorts look likely to end up with a larger share never marrying at all. That figure, and its male counterpart, appeared in a post in December 2024.

How it accumulated

Eighty-five commits over eleven years, in bursts: seventeen in 2015, then a handful a year, then a flurry whenever a new cycle landed. Between bursts the repository sat untouched for months at a time.

This is how a lot of real analysis code lives, and it is worth being honest about what it looked like after a decade:

  • About 150 files in a single directory. Raw survey data, derived data, 49 loose figures, notebooks, and the source of a 2015-era statistics library pasted into the repo rather than installed, all side by side.
  • git status reported 78 untracked files and 13 modified ones. At that point the tool stops being useful: a real change is invisible in the noise.
  • Seventeen months of uncommitted work, including a 1.8 MB notebook that produced eleven published figures and had never been committed at all.
  • Two parallel codebases. A modern one using lifelines and empiricaldist, and a legacy one using the pasted-in library — joined at exactly one function call, which kept 116 KB of 2015 code loaded on every run.
  • Data committed to version control. Several hundred megabytes of survey microdata in git-LFS — which NSFG’s data user agreement does not permit redistributing.

None of this was the result of carelessness [Thanks, Claude, but that is far too generous]. Each piece was a reasonable local decision: commit the data so the analysis is reproducible; keep a private copy of the library so it does not break; add a loader for the new cycle in the same style as the last one. The problems are emergent. No single commit introduced them.

The audit

I recently worked through the repository with Claude, with a simple standing rule: any change that was supposed to be behavior-preserving had to prove it. Before and after every structural change, the pipeline was re-run and the output compared. That rule turned out to matter more than any of the cleanup.

A one-year error in the headline variable

From cycle 10 (2015–2017) onward, the NSFG public-use files stopped publishing century-month dates of birth and marriage. What they publish instead is the year of first marriage and the integer age at interview. The loading code reconstructed the missing century months by taking midpoints:

cmbirth  = cmintvw - ager * 12 + 6      # female respondent file
cmmarrhx = (mardat01 - 1900) * 12 + 6

The marriage line is right. mardat01 is a year with no month, so mid-year is the best guess, and + 6 moves the date six months later within that year.

The birth line is not, and the sign is easy to misread, so it is worth stepping through in units of age rather than months.

Someone who reports age 30 at interview is somewhere between 30 and 31 — so the best single guess is 30.5 years old — half a year older than the integer they reported. To turn that into a birth date you go back thirty years and six further months from the interview. Going back six extra months is what - 6 does: it makes the person older, not younger.

The published code had + 6, which goes six months the other way. Concretely: for someone interviewed in January 2020 who reports age 30, - 6 gives a birth date of July 1989 and an implied age of 30.5 — the midpoint, as it should be. The + 6 gives July 1990 and an implied age of 29.5, which is younger than the age the respondent reported. Not merely biased: impossible.

Measured against cycle 9, the last cycle that still publishes a real date of birth:

formulabiasRMSE
+6 (female respondent file)+0.998 yr1.039
0 (male respondent file)+0.498 yr0.576
−6 (correct)−0.002 yr0.290

The consequence: age at first marriage was a year too low in the three most recent cycles, and correct in all the earlier ones. That distorted the trend in precisely the direction that matters. In the old data, age at first marriage fell between cycle 9 and cycle 10 — from 24.27 to 23.55 for women — a visible dip suggesting people had started marrying younger again. That dip was entirely an artifact. Corrected, the series rises monotonically across all ten cycles.

The error survived for years because it hid well. The code for the female and male respondent files was wrong in different ways that produced the same agemarry, so the two pipelines agreed with each other. And the + 6 cancels between cmbirth and cmmarrhx when you take the difference — so the headline variable looked plausible even though the birth dates underneath it were infeasible.

What found it was not reading the code. It was a sweep comparing every derived variable across every cycle boundary, looking for discontinuities.

Why the tail is hard

Now the more interesting problem, and the one that took the longest to get right.

A survival curve for a birth cohort answers: of people born in this decade, what fraction had married by each age? For the 1950s cohort that is easy — everyone in it has passed age 45, and the survey has observed them doing so.

For the 2000s cohort it is not. In the 2022–2023 survey, the oldest of them are 23. Nobody has been observed at 30. No estimator can say what fraction of them will have married by 30, because no data about it exists. This is right-censoring, and it is unavoidable — it is a property of time, not of the method.

What a Kaplan–Meier estimator does at the end of such a cohort’s range is specific and worth understanding. It tracks a risk set: the people still unmarried and still under observation. As age increases, people leave the risk set by marrying or by running out of observation. Near the end, the risk set becomes very small. When one person remains and that person marries, the estimated survival drops to zero — the curve says 100% married on the strength of a single respondent.

Look closely at the right-hand end of the 2000s curve in the published figure above and you can see the machinery straining: short, steep steps where a smooth curve should be.

The coarse dates made it worse

Here is where the missing century months come back.

In the cycles that publish real dates, age at marriage takes about 300 distinct values and age at interview about 360 — month-level resolution. In cycles 10–12, age at interview takes 36 distinct values, every one a whole number, because the file reports an integer age.

That means every censored respondent in those cycles lands on one of a dozen integer ages. The risk set does not decline smoothly; it falls off a cliff twelve times. For the 1990s cohort, 97 people are censored at age 32.000000 exactly, dropping the risk set from 131 to 34 in a single instant. Every marriage after that point moves the curve by 1.3 percentage points instead of 0.1.

So the visible spikes have two causes stacked on each other: a genuinely exhausted risk set, and an artificial one created by rounding.

What the pipeline was asserting

Step back and the deeper problem is clearer. The midpoint convention produces a number — say, age at marriage of 24.83 — and every downstream step treats that as an exactly observed time. But for cycles 10–12 both endpoints are known only to the year, so age at first marriage is genuinely uncertain by about two years.

The pipeline was reporting to the month a quantity known to within two years. The spiking tails were a symptom of that, not the disease.

What we tried

Option 1: a floor on the risk set

Stop drawing the curve once the risk set falls below some number. This is what the project was effectively doing, and it works in the narrow sense that the spikes disappear.

It has two problems. The threshold is arbitrary — I picked 10 because the figures looked right. And it treats the symptom: the curve still claims month-level precision everywhere it is drawn.

Option 2: Turnbull’s estimator

The textbook answer for interval-censored data is the Turnbull estimator, a non-parametric maximum likelihood fit that takes an interval per observation rather than a point. lifelines implements it. It is, in a real sense, the correct estimator for data of this shape.

We tried it, and rejected it for two reasons.

It does not fix the tail. On the 2000s cohort it reads 12.88% at age 23.2 and then jumps to 100% — the same degeneracy as Kaplan–Meier, for the same reason. When the risk set is exhausted, the likelihood puts all remaining mass in the last interval. Being correct about the censoring structure buys nothing once the data runs out.

And it does not scale. It took 1.1 seconds on a cohort of 2,140 and more than five minutes on one of 16,169 without finishing. Inside a bootstrap, where it would run hundreds of times, that is not viable.

Option 3: multiple imputation

Instead of collapsing each interval to its midpoint, draw a value from inside it. Draw the birth date uniformly within the year it could have been; draw the marriage date uniformly within its year; compute age at marriage from the draws. Repeat.

This is the option we adopted, but the reason is not the one I expected. It does not smooth the curve — individual draws still spike. What it does is make the instability visible. Five draws for the 2000s cohort gave final estimates of 100%, 17%, 13%, 12% and 11%.

That is a ninety-point spread on identical data, because at that age the answer turns on whether one person’s imputed marriage date happens to fall before or after their imputed censoring date. The midpoint convention picks one of those numbers and reports it without a warning. The imputation reports the spread, which is the honest answer: at this age, this data cannot tell you.

The rule we settled on

That spread becomes the stopping rule. Fit the curve to many draws, report the mean, and stop where the draws stop agreeing.

Getting the criterion right took two failures, and both are instructive.

An absolute threshold does not work. Stop where the spread exceeds two percentage points, and a small cohort loses everything: 322 men born in the 1950s have a bootstrap spread near two points at every age, simply because the cohort is small. The rule truncated that curve at age 21 and discarded it.

A purely relative threshold does not work either. Stop where the spread exceeds three times the cohort’s own median, and precision is punished: the 1990s cohort has a median spread of 0.4 points, so it trips at 1.2 points — an entirely reportable estimate.

Neither criterion alone separates “the tail has degenerated” from “this cohort is small”. Together they do. A point is dropped only if it is anomalous for its own cohort and imprecise in absolute terms: drop where sd>max(floor,k×median(sd))

The diagnostic below shows it working. Each line is one cohort’s bootstrap spread divided by its own median — solid for women, dashed for men — and the dotted line is the relative threshold. The 1930s women’s curve peaks at 2.2× around age 20 and is kept, because in absolute terms it is still precise. The 1990s and 2000s curves climb past the threshold and are cut.

Where each estimate stops being reportable

The result

Estimation is now a bootstrap that resamples respondents within cycle by sampling weight and then draws from each respondent’s interval, so the spread across iterations carries sampling variability and date coarseness together.

In the figures below, the shaded band around each curve is a 90% bootstrap interval, and the dot marks the age past which the data no longer supports an estimate — the point where the stopping rule cuts the curve off.

Percent ever married, women, by decade of birth
Percent ever married, men, by decade of birth

The substantive story is unchanged: each cohort still marries later than the last, and the recent cohorts still look likely to end with a larger share never married. An audit that overturned the finding would be a bigger story; this one did not.

But some of the numbers changed. For women in the 1990s cohort the old pipeline reported about 62% ever married by age 33; the new one reports 56.5% by 32. Most of that gap is the censoring correction: retiring people from the risk set half a year too early removes them before marriages they may have had, which inflates the estimate.

What I take from this

The valuable output was not the cleanup. Reorganizing 150 files into directories, purging the data from git history, converting notebooks to markdown, retiring the pasted-in library — all worth doing, none of it interesting. The valuable output was three bugs and a method, and every one of them came from the same discipline: check that the thing you believe is true.

Verification is what made the agentic part work. The rule that every supposedly behavior-preserving change had to produce a byte-identical result is what made it safe to delete 253 lines of unreachable code, retire a library that had been pasted in a decade ago, rename 39 functions, and move every file in the repository. It is also what caught the errors. Only one of them had reached the published figures — the reconstructed date of birth, wrong since 2019 — and it was found by a sweep comparing derived variables across cycle boundaries, not by anybody reading the code. The rest were Claude’s, made and caught within the session, before they could change a number.

Coarsened data deserves explicit handling. When NSFG stopped publishing century-month dates, the pipeline papered over it with a midpoint and carried on. That was the single decision that caused both the year-long bias and the spiking tails. The honest move — say what you know, which is an interval — was available the whole time.

Some questions have no answer, and saying so is the finding. No estimator can tell you what fraction of people born in the 2000s will have married by 30. The best a method can do is be clear about where its knowledge ends. A curve that stops, with a dot, is more informative than one that continues into a spike.


The code is at AllenDowney/MarriageNSFG. The estimation lives in nsfg/intervals.py and scripts/estimate_marriage.py; the figures come from scripts/plot_marriage.py.

Note for AI text detectors: Yes, most of this post was generated by Claude, as acknowledged in the introduction.
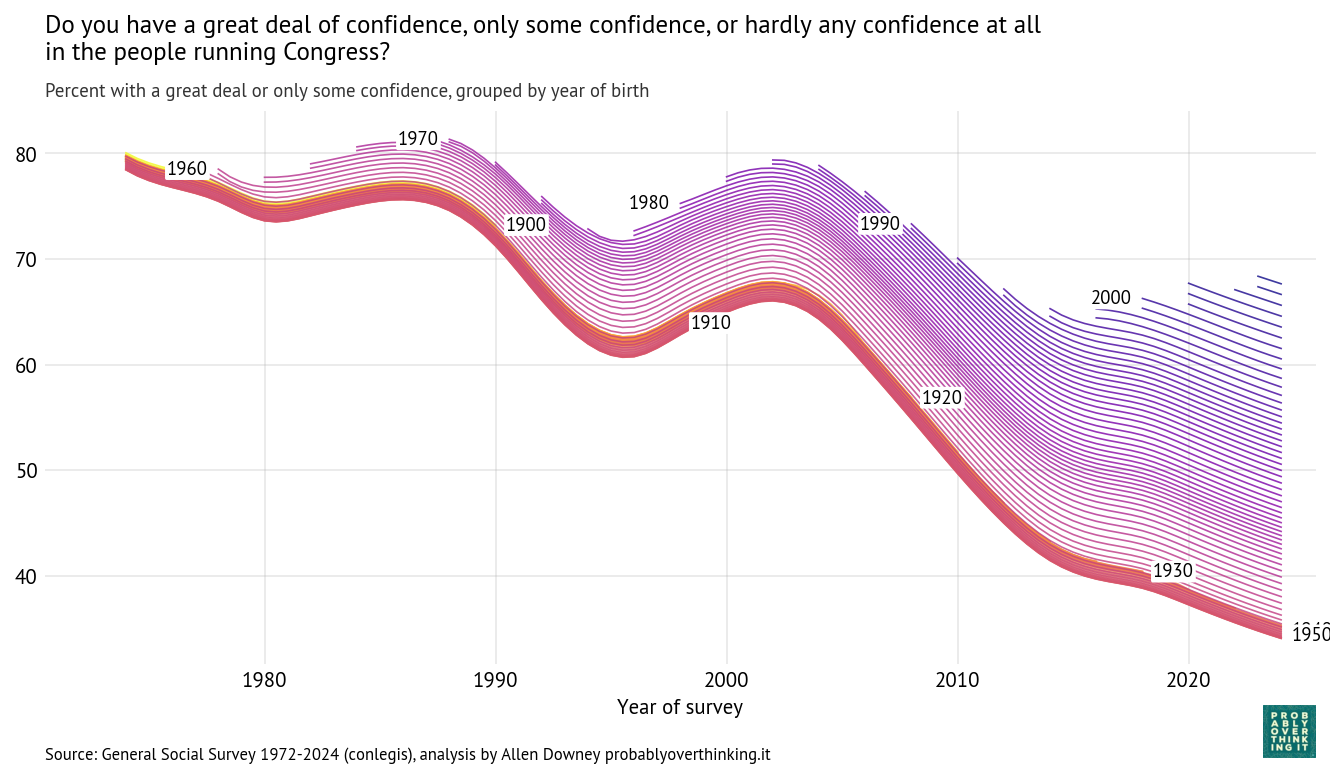
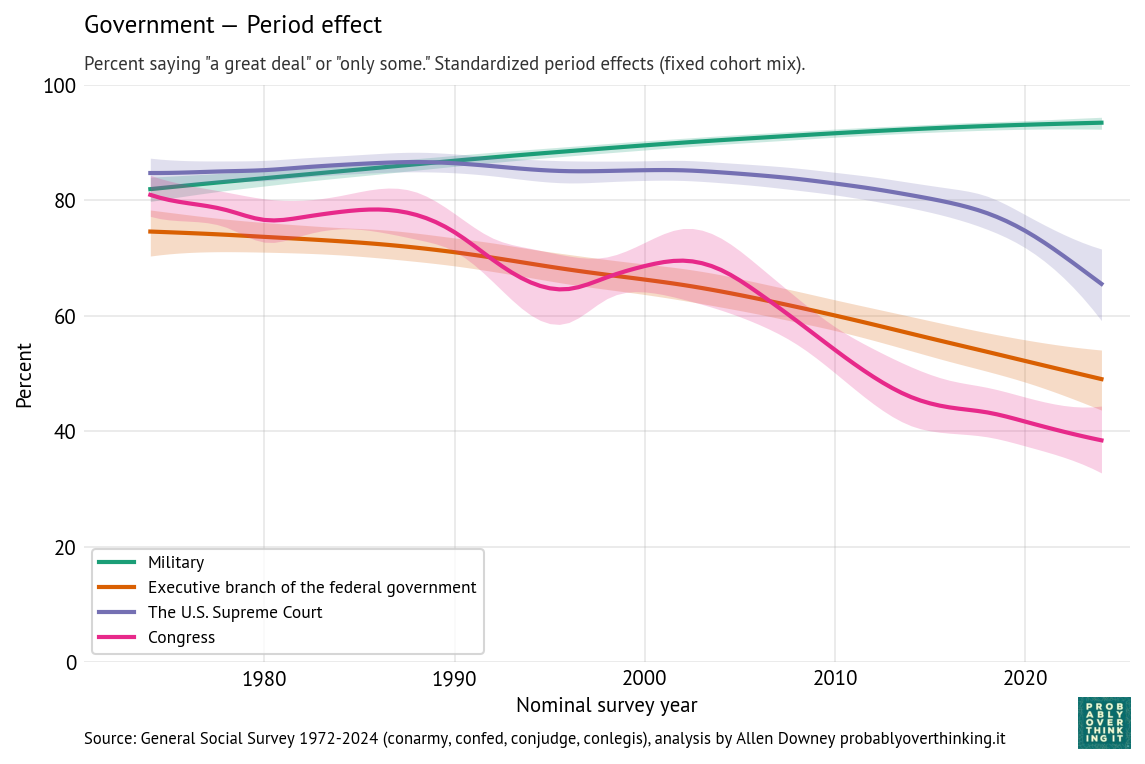
New Book!

New Book!

I am working on a new book called You Would Choose Now: Measuring America’s Progress Toward Fairness and Tolerance. It’s a data-driven exploration of progress (or not) in public opinion and civil rights.

I posted the first two chapters as an Early Access edition on LeanPub (a platform for posting work in progress like this): https://leanpub.com/ywcn

If you would like to check it out, the “Free Sample” has just the first chapter. If you sign up with an email address, you can get the “Community Edition”, which has the first two chapters — and that’s all there are for now. Chapter 3 is scheduled for October 1.

As I add chapters over the next six months, I will post excerpts on Substack. So if you only follow this blog and not my Substack, you might want to sign up over there. I will continue to post on other topics here.

What’s it about?

If you read this post from a couple of weeks ago, you already know the premise of the book: in 2016, Barack Obama gave a commencement address at Howard University, where he said

If you had to choose one moment in history in which you could be born, and you didn’t know ahead of time who you were going to be — what nationality, what gender, what race, whether you’d be rich or poor, gay or straight, what faith you’d be born into — you wouldn’t choose 100 years ago. You wouldn’t choose the fifties, or the sixties, or the seventies. You’d choose right now.

That was a bold thing to say to new college graduates, even in 2016. So I read Obama’s address with a skeptical eye. I wondered if he was right in 2016, and if so, whether he would still be right in 2026. And I thought about how to prove or disprove it. That’s what the book is about.

Chapter 1 is an introduction that includes an example of the primary statistical method I’ll use, period-cohort analysis. Chapter 2 is about sexual orientation. I plan to publish Chapter 3, which is about gender, on October 1. And then Chapter 4, about race, on November 1.

Part of the reason I am publishing incrementally is to encourage reader feedback, so I welcome comments and suggestions.

And if you are interested in the technical details, there’s an appendix that explains the analysis.

Think Java, but interactive

Think Java, but interactive

The online version of Think Java now features interactive widgets that run the code examples in the browser. For readers, it means you can try out the examples, modify them, and test your code. And for us it means we can publish an interactive version of the book without providing servers.

The widgets use java-runner, an in-browser Java editor and interpreter developed by Think Java co-author Chris Mayfield.

java-runner implements a subset of Java with the features needed for most programming classes, plus some safety features — like a maximum instruction count to stop infinite loops. It provides a code editor and a REPL.

Here’s an example of the code editor, from Section 6.1:

And here’s an example of the REPL, from Section 6.6::

We’re aware of one example where the behavior of java-runner differs from the Java language specification — so we’re working on that.

Greatest GOAT of All Time?

Greatest GOAT of All Time?

A recent post claims that the “most statistically dominant athlete” of all time was cricketer Don Bradman. It’s a bold claim – let’s see if it holds up.

In Chapter 4 of Probably Overthinking It, I listed a few examples of athletes who are considered the Greatest Of All Time (GOAT), and noted that in many cases they are not just a little better than the second-best, but much better. That is, they are outliers among outliers.

And I suggested that part of the explanation for this phenomenon is that the distribution of accomplishment in many fields (at least, the ones where accomplishment can be quantified) follows a lognormal distribution. That matters because the lognormal distribution has a long tail, which means that extreme values can be much farther from the mean than we would see in a Gaussian (normal) distribution.

So I was intrigued by this post about Don Bradman:

The most statistically dominant athlete ever isn’t Jordan or Messi — and you’ve probably never heard of him. 🏏

I plotted the career batting averages of the greatest Test cricketers of all time. They make a clean bell curve. In cricket, averaging 50 makes you an immortal legend, and the all-time record holders top out around 60 — about 2 standard deviations above the mean.

Then there’s Don Bradman: 99.94. More than 6 standard deviations out. The gap between him and the SECOND best player is bigger than the gap between #2 and the entire average. By the math, a batsman this good should appear about once in 7 billion.

To be this far ahead in basketball, Michael Jordan would’ve had to average 43 points in every single game he ever played. No one in any sport — not Jordan, not Gretzky, not Messi — is this far from their peers.

Not just the greatest. The single biggest outlier in the history of sport.

Let’s see if that’s true. In particular, I’ll investigate the “clean bell curve” – it implies a Gaussian model of the data, which is where that “once in 7 billion” comes from.

To give away the ending, here’s what I found:

  • The data don’t fit a Gaussian particularly well, especially in the tail, so the “one in 7 billion” might not be right.
  • I thought they might fit a lognormal better, but I was wrong.
  • It turns out that the data fit a Weibull distribution very well, and from that we can get a revised estimate of how much of a GOAT Bradman was.

As it turns out, he was a pretty goaty GOAT – but not quite one in 7 billion.

Load the data

I got the data from Kaggle (runs_of_batsmen.csv).

DATA_PATH = "runs_of_batsmen.csv"

df = pd.read_csv(DATA_PATH)

# Convert to numeric, coercing errors to NaN
df['Batting Average'] = pd.to_numeric(df['Batting Average'], errors='coerce')
df['Innings'] = pd.to_numeric(df['Innings'], errors='coerce')

I select only batters with 10 or more innings.

df = df.query('Innings >= 10')

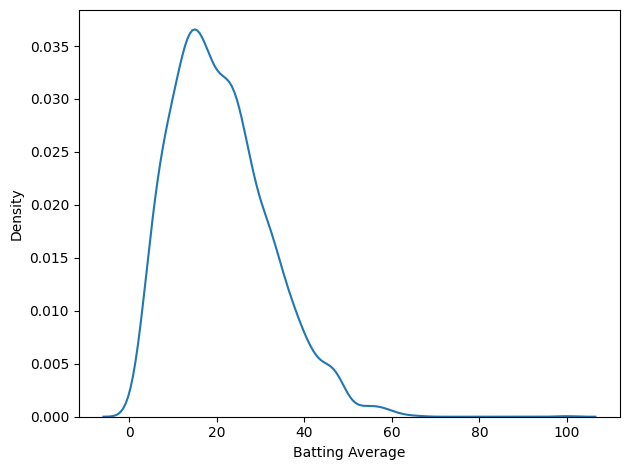
Here’s what the distribution of batting averages looks like.

import seaborn as sns

sns.kdeplot(df['Batting Average'])
decorate()
_images/9e6e3e754fa48807f6d4f5b72552714ed01e3d2dec5cfb8bb37abb5ad845d7aa.png

That’s not much of a bell curve. It’s pretty clearly skewed to the right, even if we leave Bradman out of it. But let’s fit a Gaussian to it anyway.

The Gaussian Model

There are a lot of ways to fit a model to data. The one I like for applications like this is percentile matching – that is, finding a model that minimizes the average vertical distance between the empirical CDF of the data and the CDF of the model. That’s what fit_normal does.

avg_series = df["Batting Average"].dropna()
gaussian_model = fit_normal(avg_series)

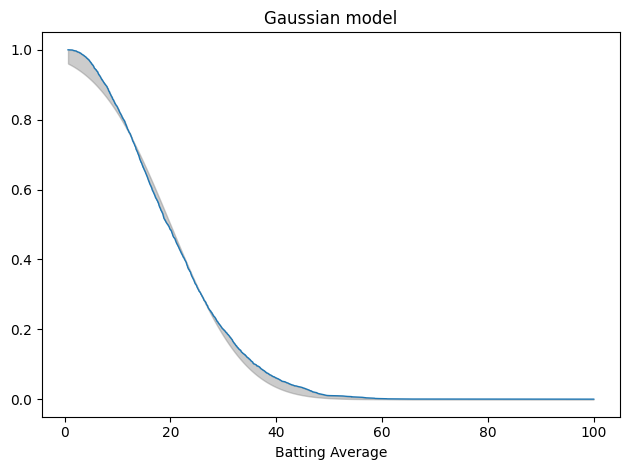
Here’s what that looks like, plotting the tail distribution, which is the complement of the CDF. The shaded area shows the differences between the data and the model.

tail_data = TailDist.from_seq(avg_series)
plot_fit_with_area(tail_data, gaussian_model, kind="tail")
decorate(xlabel="Batting Average", title='Gaussian model')
_images/4b2c95fa3fda1563ca2714d6361e97b106ed1984db9479b168798ca548a9d940.png

This is not a great fit. There are clear differences in the shapes of the tail distributions.

And here’s the average error, which is related to the area between the curves.

mae_normal = average_error(avg_series, gaussian_model)
mae_normal
0.017745997600540485

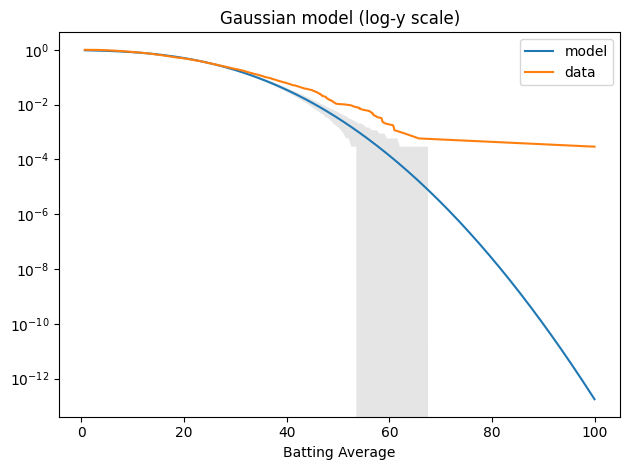
When we plot the tail distributions on linear scales, it looks like the model might be good enough. The problem is that we can’t see what’s happening in the tail. For that, it’s useful to plot the tail distributions on a log-y scale.

n = len(avg_series)
qs = np.linspace(tail_data.qs.min(), tail_data.qs.max(), 200)
tail_model = TailDist(gaussian_model.sf(qs), index=qs)
plot_model_bounds(gaussian_model, n=n, qs=qs, kind="tail", color="gray", alpha=0.2)
tail_model.plot(label="model")
tail_data.plot(label="data")
decorate(yscale="log", title='Gaussian model (log-y scale)')
_images/b8bccf875d3216eb826852be8de578e37cbfb0909184ce61df747e79bef1db5e.png

The model fits the left side of the distribution well enough, but after that, it diverges badly. Around 60, the difference between the model and the data is about an order of magnitude.

Nevertheless, we can use the Gaussian model to compute the probability of a batting average as high as Bradman’s 99.94.

BRADMAN = 99.94


def probability_of_exceeding(model, x, n):
    p = model.cdf(x)
    one_in = 1 / (1 - p)
    in_sample = 1 / (1 - p ** n)
    return one_in, in_sample

In the fitted distribution, the probability of a single batter achieving Bradman’s average is about one per 5.7 trillion.

one_in, in_sample = probability_of_exceeding(gaussian_model, BRADMAN, n)
one_in / 1e12
5.71160383940456

And even if we account for the sample size, the probability that one of 3438 batsman reaches that level is one per 1.7 billion. So, according to the Gaussian model, this outcome is basically impossible.

n, in_sample / 1e9
(3438, 1.6613158346144736)

But the Gaussian model doesn’t fit the data well – and there’s no reason it should. To see why not, let’s think about the process that generates the distribution of batting averages.

As a simplifying assumption, suppose a batsman has the same probability of getting out at any time; in that case, the number of runs in an inning might follow a negative binomial (NB) distribution. As we add up innings (or average over them), the total would eventually converge to a normal distribution, but most batsmans don’t have enough innings to converge. So for each batsman, the distribution of runs follows something between NB and normal. And when we combine them, we get a mixture of those hybrids. There’s no obvious reason the results should fit a simple mathematical model.

But it turns out that they do.

The Weibull Model

The Weibull distribution is not the first thing I thought of – I tried a lognormal distribution first. But a Weibull distribution fits the data really, really well. The fit_scipy_dist is a more general version of fit_normal that works with any of the SciPy distributions.

weibull_model = fit_scipy_dist(avg_series, weibull_min)
weibull_model.args
(1.8667199063293203, 0.9939717502596944, 22.486446489455503)

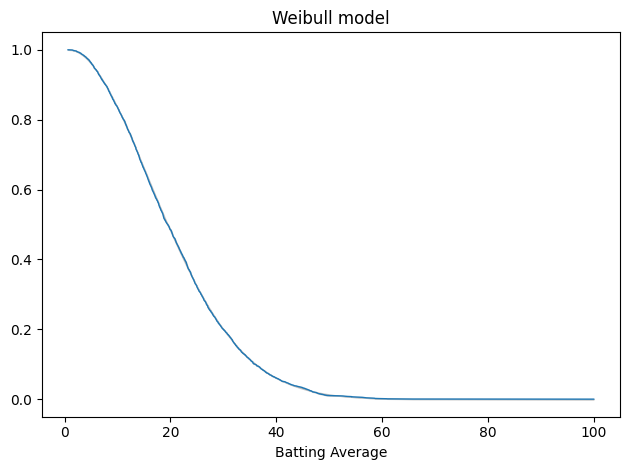
Here’s the result. Again, the gray area shows the difference between the data and the model.

plot_fit_with_area(tail_data, weibull_model, kind="tail")
decorate(xlabel="Batting Average", title="Weibull model")
_images/2c9b224b40833eea766b5d0cd386fc20182601b3ae5245f8f68f7ffca163a4cf.png

The gray area is not visible. Here’s the average error.

mae_weibull = average_error(avg_series, weibull_model)
mae_weibull
0.002555441381799216

The average error of the Gaussian model is about 7x bigger.

mae_normal / mae_weibull
6.944396270223196

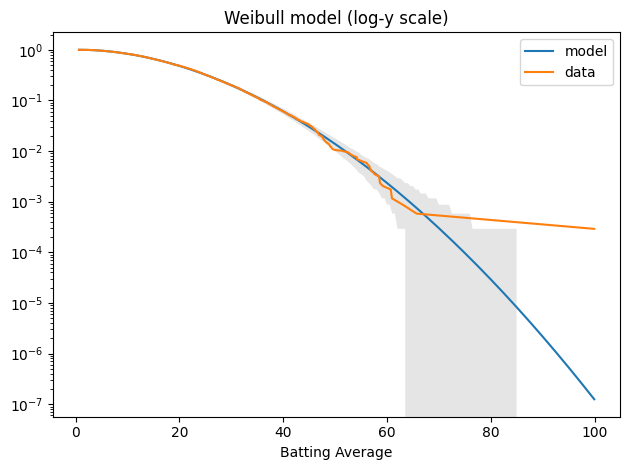
Here’s what the tail looks like on a log-y axis.

tail_model = TailDist(weibull_model.sf(qs), index=qs)
plot_model_bounds(weibull_model, n=n, qs=qs, kind="tail", color="gray", alpha=0.2)
tail_model.plot(label="model")
tail_data.plot(label="data")
decorate(yscale="log", title="Weibull model (log-y scale)")
_images/b42367fb1469d102aa278bd0b6f4c1a339ea7f78a8919fd2da3d27b61c2e3fc3.png

The model fits the data well – within the bounds of variability we expect for this sample size – except for Bradman, who is still an outlier.

Again, we can compute the probability that any batter exceeds Bradman’s level:

one_in, in_sample = probability_of_exceeding(weibull_model, BRADMAN, n)
one_in / 1e6
7.980438255436601

It’s about one per 8 million. And in a sample of 3438 batsmen, the chance that any one of them reaches that level is one per 2,322.

in_sample / 1e3
2.3217442928624186

So Bradman is still an outlier among outliers, but not quite the statistical anomaly that he would be in a normal distribution.

Finally, let’s think about why a Weibull distribution fits this dataset so well. In the data-generating process I suggested earlier, if a batsman has the same probability of getting out at any time, the number of runs in an inning might follow a negative binomial (NB) distribution. If we think of the run-generating process as continuous, the distribution of runs before an out would be exponential. And if we relax the assumption that the hazard rate is constant, the distribution of runs per inning would be Weibull.

I think that’s an intriguing first step, but at best it explains the distribution of runs per inning – but not the distribution of batting averages across batsmen with, presumably, different hazard rates.

Appendix: The Lognormal Model

Just for completeness, here’s the lognormal model.

log_series = np.log10(avg_series)
log_model = fit_normal(log_series, x0=norm.fit(log_series))
tail_log_data = TailDist.from_seq(log_series)
plot_fit_with_area(tail_log_data, log_model, kind="tail")
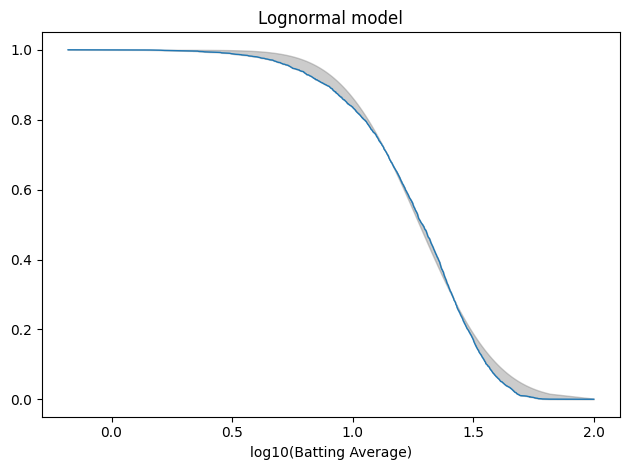
decorate(xlabel="log10(Batting Average)", title="Lognormal model")
_images/6344bb082e43613d7cc8910ef8f34769e420045404b8d576f8382bc64b0c8bc2.png

The average error is slightly worse than the Gaussian model.

mae_lognormal = average_error(log_series, log_model)
mae_lognormal
0.01885918996726559

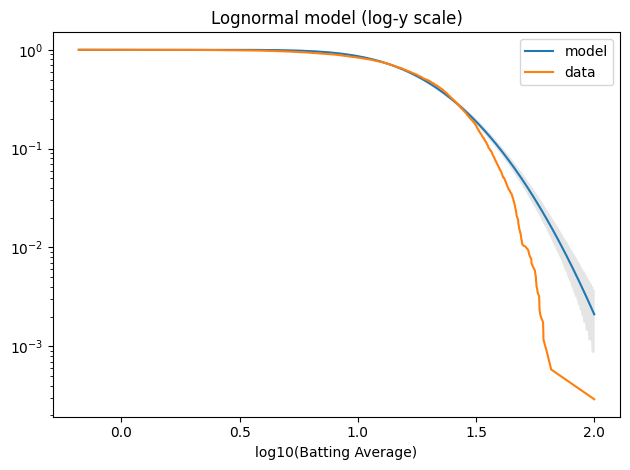
And it doesn’t fit the tail well at all.

log_qs = np.log10(qs)
tail_model = TailDist(log_model.sf(log_qs), index=log_qs)
plot_model_bounds(log_model, n=n, qs=log_qs, kind="tail", color="gray", alpha=0.2)
tail_model.plot(label="model")
tail_log_data.plot(label="data")
decorate(xlabel="log10(Batting Average)", yscale="log", title="Lognormal model (log-y scale)")
_images/5d0319f985ddb2ca9f541683b89a467e19b0e12c468c4c00b5a969111401be6b.png

The Frog Puzzle

The Frog Puzzle

Here’s a probability puzzle from a TED-Ed video called Can you solve the frog riddle? by Derek Abbott. It came up recently in this Reddit thread:

You’re stranded in a rainforest after accidentally eating a poisonous mushroom. To survive the poison, you need to lick a certain species of frog. Only female frogs produce the antidote. Male and female frogs occur in equal numbers and look identical, but male frogs have a distinctive croak.

You see one frog alone on a tree stump. In another direction, you hear the croak of a male frog coming from a clearing with two frogs. You can’t tell which one made the sound.

You only have time to go to one place. What are your chances of survival if you go to the clearing and lick both frogs? What if you go to the lone frog?

The second question is relatively easy: if we assume that you are equally likely to see a male or female frog, the probability is 50% that the lone frog is female.

The first question depends on how we interpret the puzzle. In particular, it hinges on the word “distinctive” – does that mean:

  • Only male frogs croak, and the sound is distinguishable from background noises, or
  • Both male and female frogs croak, but the male croak is distinguishable from the female croak.

Based on the answer presented in the video, the first meaning is intended. So we’ll start by solving that version.

But the second meaning makes the problem a little harder, so we’ll solve that one, too.

Only Male Frogs Croak

To solve the intended version of the puzzle, we’ll assume

  • Only male frogs croak, and
  • When two frogs appear together, their sexes are independent.

So we’ll start with a prior where all two-frog combinations are equally likely.

from sympy import Rational

hypo = ['FF', 'FM', 'MF', 'MM']
prior = Rational(1)

Now let’s think about the likelihood of the data under each scenario. In the video, the solution is based on these assumptions:

  • If both frogs are female, the probability of hearing the male croak is 0.
  • If either frog is male, the probability that one of them croaks is 1.
likelihood = [0, 1, 1, 1]

I’ll use a BayesTable to compute the posterior probability for each scenario.

import pandas as pd
import numpy as np

class BayesTable(pd.DataFrame):
    def __init__(self, hypo, prior=1, **options):
        columns = ['prior', 'likelihood', 'unnorm', 'posterior']
        super().__init__(index=hypo, columns=columns, **options)
        self.prior = prior
    
    def update(self, likelihood):
        self.likelihood = likelihood
        self.unnorm = self.prior * self.likelihood
        nc = self.unnorm.sum()
        self.posterior = self.unnorm / nc
table = BayesTable(hypo, prior)
table.update(likelihood)
table
priorlikelihoodunnormposterior
FF1000
FM1111/3
MF1111/3
MM1111/3

From the table, we can extract the posterior probability that both frogs are male.

from sympy import init_printing
init_printing(use_latex=False)
table.posterior['MM']
1/3

With these assumptions, the probability 1/3 that both frogs are male (and you die), so the probability is 2/3 that at least one is female (and you live).

And that’s the answer in the video.

Poisson (not Poison) Frogs

But is that the right likelihood? Suppose frogs are equally likely to croak at any instant in time, so their croaks follow a Poisson process. If we assume that these croaking processes are independent, two frogs would be more likely to croak, during a given interval, than one.

If the interval is much longer than the average time between croaks, the probability that either frog croaks approaches 1, which is consistent with the previous solution.

But if the interval is short – as it might be if you were deciding whether to approach the first frog – the probability of hearing a croak would be double if there are two male frogs rather than one.

In that case, the likelihood of the data would be:

half = Rational(1, 2)
likelihood = [0, half, half, 1]

And here are the posterior probabilities:

table = BayesTable(hypo, prior)
table.update(likelihood)
table
priorlikelihoodunnormposterior
FF1000
FM11/21/21/4
MF11/21/21/4
MM1111/2

With Poisson frogs and a short interval, the probability of two male frogs is 1/2, so it doesn’t matter whether you approach the lone frog or the pair of frogs.

Female Frogs Croak, Too

Now let’s think about the other interpretation of the puzzle: suppose both male and female frogs croak, but we can distinguish one from the other. And suppose male and female frogs croak at different rates, but they are still independent.

Assume that male frogs croak at a rate of 1 per time unit, and female frogs at a rate of r per time unit. In that case, if we start listening at a random time, the probability that we hear a male frog first is 1 / (r+1) if there’s only one male frog, and 1 if there are two male frogs.

So the likelihood in this case is:

from sympy import symbols

r = symbols('r')
likelihood = [0, 1 / (r+1), 1 / (r+1), 1]

And here are the posteriors

table = BayesTable(hypo, prior)
table.update(likelihood)
table
priorlikelihoodunnormposterior
FF1000
FM11/(r + 1)1/(r + 1)1/((1 + 2/(r + 1))*(r + 1))
MF11/(r + 1)1/(r + 1)1/((1 + 2/(r + 1))*(r + 1))
MM1111/(1 + 2/(r + 1))

In this scenario, here’s the probability you die.

prob_die = table.posterior['MM']
prob_die.simplify()
r + 1
─────
r + 3

If female frogs don’t croak, we get the same answer as in the first scenario.

prob_die.subs({r: 0})
1/3

If male and female frogs croak at the same rate, the probability that both frogs are male is 1/2.

prob_die.subs({r: 1})
1/2

But if female frogs croak much more often, the fact that a male croaked first is strong evidence that both are male, so the posterior probability is close to 1.

prob_die.subs({r: 1000}).evalf()
0.998005982053839

Assortative Mating

Now suppose that when we see two frogs together, their sexes are not independent; specifically, let’s assume that the probability of a same-sex pair is p, so the probability of a mixed-sex pair is 1-p. In this scenario, the priors (before we hear the croak) are not equal.

p = symbols('p')
prior = [p, 1-p, 1-p, p]

Here are the posterior probabilities, assuming again that both male and female frogs, possibly at different rates.

likelihood = [0, 1 / (r+1), 1 / (r+1), 1]
table = BayesTable(hypo, prior)
table.update(likelihood)
table
priorlikelihoodunnormposterior
FFp000
FM1 – p1/(r + 1)(1 – p)/(r + 1)(1 – p)/((p + 2*(1 – p)/(r + 1))*(r + 1))
MF1 – p1/(r + 1)(1 – p)/(r + 1)(1 – p)/((p + 2*(1 – p)/(r + 1))*(r + 1))
MMp1pp/(p + 2*(1 – p)/(r + 1))
table.posterior['MM'].simplify()
 p⋅(r + 1) 
───────────
p⋅r - p + 2

If p=1/2, this simplifies to the previous scenario.

table.posterior['MM'].subs({p: half}).simplify()
r + 1
─────
r + 3

And if r=0 (female frogs don’t croak), we get the answer presented in the video.

table.posterior['MM'].subs({p: half, r: 0}).simplify()
1/3

But depending on the assumptions, the probability can be as low as 0

table.posterior['MM'].subs({p: 0, r: 1}).simplify()
0

Or as high as 1.

table.posterior['MM'].subs({p: 1, r: 0}).simplify()
1

Or anything in between. As is often the case with problems like these, the answer depends on a precise specification of the data-generating process.

Discussion

If all of this seems like more trouble than it’s worth, let me suggest a metacognitive shortcut for solving puzzles like this.

  1. Notice that in all probability puzzles, the answer is either 1/2 or 1/3.
  2. Also, the answer is always counterintuitive; otherwise it wouldn’t be a puzzle.
  3. Therefore, if your intuition says the answer is 1/2, it’s actually 1/3, and vice versa.

That might save you some time.

This notebook uses methods and materials from Think Bayes, second edition. If you like this sort of thing, you can read the whole book, and more examples, at allendowney.github.io/ThinkBayes2/.


Planning for your midlife crisis

Planning for your midlife crisis

Yesterday I presented a talk at ODSC East 2026, called “Counterfactual Analysis with Bayesian Models: What Drives the Life Expectancy Gap?” Here’s the abstract

Across nearly every country in the world, women live longer than men—but the size of this gap varies from about two years in some countries to more than twelve in others. What explains these differences, and how much of the gap can be closed?

In this talk, I present a practical approach to counterfactual analysis using Bayesian regression models. Using publicly available mortality data, we build a model that relates the life expectancy gap between men and women to differences in cause-specific death rates, including homicide, drug overdoses, traffic fatalities, smoking-related disease, and chronic illness.

The model generates posterior simulations that answer “what-if” questions. For example: How much smaller would the U.S. life expectancy gap be if homicide rates matched those in Western Europe?

The talk presents the workflow—from assembling global datasets to fitting interpretable Bayesian models with PyMC and generating counterfactual simulations. Attendees will learn how Bayesian models can support explainable modeling and analysis under uncertainty.

I think the talk went well, and we got some good questions at the end. There’s no recording, unfortunately, but my slides are here. And if you want to know more, I have a series of blog posts on Substack

The fifth and final post is on the way. In the meantime, here’s a quick post on a related topic.

Are you middle-aged?

Here’s a question from Reddit’s Stupid Questions forum:

I always thought middle age was in your 40s but since life expectancy is around 75 or so, wouldn’t it be about 35?

If life expectancy is 75, you might think the midpoint is half that, which is 37.5. But if 75 is life expectancy at birth and you survive to age 37.5, your life expectancy at that age is higher than 75. So 37.5 is not halfway!

If we really want to find the midpoint – and it wouldn’t be Probably Overthinking It if we didn’t – we have to find the age where your expected remaining lifetime equals your current age.

Let’s do it.

Data

From the Human Mortality Database I downloaded life tables for the United States, combined and broken down for men and women. The following function reads and cleans a table.

def read_life_table(filename):
    lt = pd.read_fwf(filename, skiprows=2, infer_nrows=200)
    lt['Age'] = lt['Age'].str.replace('+', '', regex=False).astype(int)
    return lt

Here are the first few rows of the combined table (see notes below for details).

blt = read_life_table('../data/bltper_1x1.txt')
blt.head()
YearAgemxqxaxlxdxLxTxex
0193300.061290.058610.25100000586195624608960960.90
1193310.009460.009410.509413988693696599398563.67
2193320.004350.004340.509325340593050590028963.27
3193330.003100.003100.509284828892704580723962.55
4193340.002390.002380.509256022192450571453561.74

We’ll also read the female and male tables.

flt = read_life_table('../data/fltper_1x1.txt')
mlt = read_life_table('../data/mltper_1x1.txt')

The tables include data from 1933 to 2024, so we’ll select the most recent data.

year = blt['Year'].unique()[-1]
table = blt.query('Year == @year').set_index('Age')

The column we’ll use is ex, which is life expectancy as a function of age.

age = table.index.to_series()
ex = table['ex']

Life expectancy at birth is 79 years, so the naive midpoint is 39.5.

ex[0], ex[0] / 2
(79.08, 39.54)

But at age 40, expected remaining lifetime is 41.1, so 39.5 is not the midpoint.

ex[39], ex[40]
(42.04, 41.12)

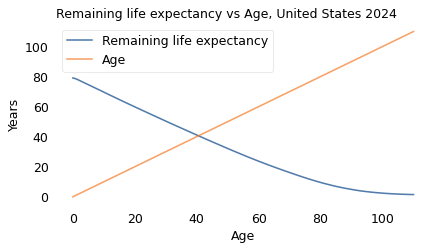
This plot shows life expectancy at each age, compared to age.

ex.plot(label='Remaining life expectancy')
age.plot(label='Age')
decorate(ylabel='Years',
        title='Remaining life expectancy vs age, United States 2024')
_images/a55e9cbde25b36d9c42e2ede2a78a827460d537f230b5cc4e7dfcb519a44bbc6.png

“Middle age” is where the lines cross, which we can compute by linear interpolation.

from scipy.interpolate import interp1d

inverse = interp1d(ex - age, age)
inverse(0)
array(40.58638743)

So the overall midpoint is 40.6 years. But as you might expect, it’s different for men and women. Let’s put the analysis we did in a function.
def get_midpoint(filename):
    lt = read_life_table(filename)
    year = lt['Year'].unique()[-1]
    table = lt.query('Year == @year').set_index('Age')

    age = pd.Series(table.index)
    ex = table['ex']

    inverse = interp1d(ex - age, age)
    return inverse(0)

And run it for men.
get_midpoint('../data/mltper_1x1.txt')
array(39.57142857)

And women.
get_midpoint('../data/fltper_1x1.txt')
array(41.56185567)

Men hit middle age at 39.6, women at 41.6.

The Gender Gap and Age

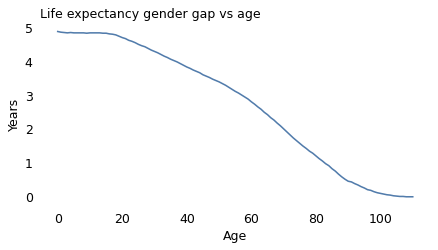
Finally, let’s see how the gender gap in life expectancy changes as a function of age.

ex_male = mlt.query('Year == @year').set_index('Age')['ex']
ex_female = flt.query('Year == @year').set_index('Age')['ex']
gap = ex_female - ex_male
gap.plot(label='')
decorate(ylabel='Years',
         title='Life expectancy gender gap vs age')
_images/2cf48be5acc971ad8f6973506c224767a25ef2e38bcf53c5b12b0f895c26ed11.png

At birth the life expectancy gap is close to five years. At age 100, it is close to zero.

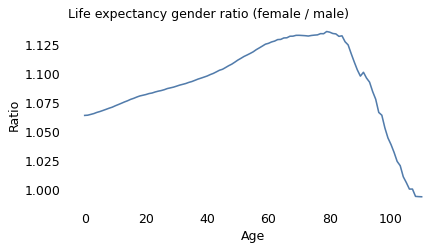
But just looking at the gap might be misleading. For a more complete picture let’s also look at the ratio.

ratio = ex_female / ex_male
ratio.plot(label='')

decorate(ylabel='Ratio',
         title='Life expectancy gender ratio (female / male)')
_images/1a514d22895c3e18a767184700d6edf467975abb4b302afe044fd42c002ae21c.png

The life expectancy ratio tells a more complicated story.

  • At birth, the ratio is 1.06, which means female babies live 6% longer, on average.
  • Around age 80, the ratio peaks at nearly 1.14 – so between female and male octogenarians, we expect the women to live 14% longer.
  • At advanced ages, the ratio declines steeply and actually crosses over after age 100 – although the crossover is minimal and might not be statistically valid.

To interpret these results, we can think about the causes of death that contribute to age-specific death rates at different stages of life.

  • In young adulthood, the causes of death that contribute most to gender gaps include road traffic, homicide, accidental injury, drug use disorders.
  • In advanced adulthood, they include cancer, cardiovascular disease, respiratory disease, liver disease, diabetes, and suicide.

The causes that affect younger people have large gender gaps, but relatively low death rates. As people get older, these low-rate causes contribute less to age-specific death rates, and the higher-rate causes contribute more.

I think that’s a plausible explanation for the increasing ratio from age 0 to 80. For the decline that follows, I can only speculate that there is a selection effect: people who get to these advanced ages are likely to have better-than-average lifestyle histories (less smoking and drinking, better diet, more exercise) – and among people with better lifestyles, the gender gap is small.

Notes

Data credit: HMD. Human Mortality Database. Max Planck Institute for Demographic Research (Germany), University of California, Berkeley (USA), and French Institute for Demographic Studies (France). Available at [www.mortality.org].

Here are the columns of the 1×1 Period Life Tables:

  • Year: Calendar year to which the period life table refers.
  • Age: Exact age (x), in years, at the beginning of the interval ([x, x+1)).
  • mx: Central death rate at age (x):
  • qx: Probability of dying between ages (x) and (x+1):
  • ax: Average fraction of the interval lived by those who die in ([x, x+1)). Typically around 0.5 for most ages, lower for infants (reflecting higher early mortality within the year).
  • lx: Number of survivors at exact age (x), out of a radix (usually 100,000 births).
  • dx: Number of deaths between ages (x) and (x+1):
  • Lx: Person-years lived between ages (x) and (x+1), approximately
  • Tx: Total person-years remaining above age (x):
  • ex: Life expectancy at age (x):

The details are in this Jupyter notebook.